Morning Brief
A self-hosted daily news essay: around 80 sources read, triaged and written up with citations before 06:15.
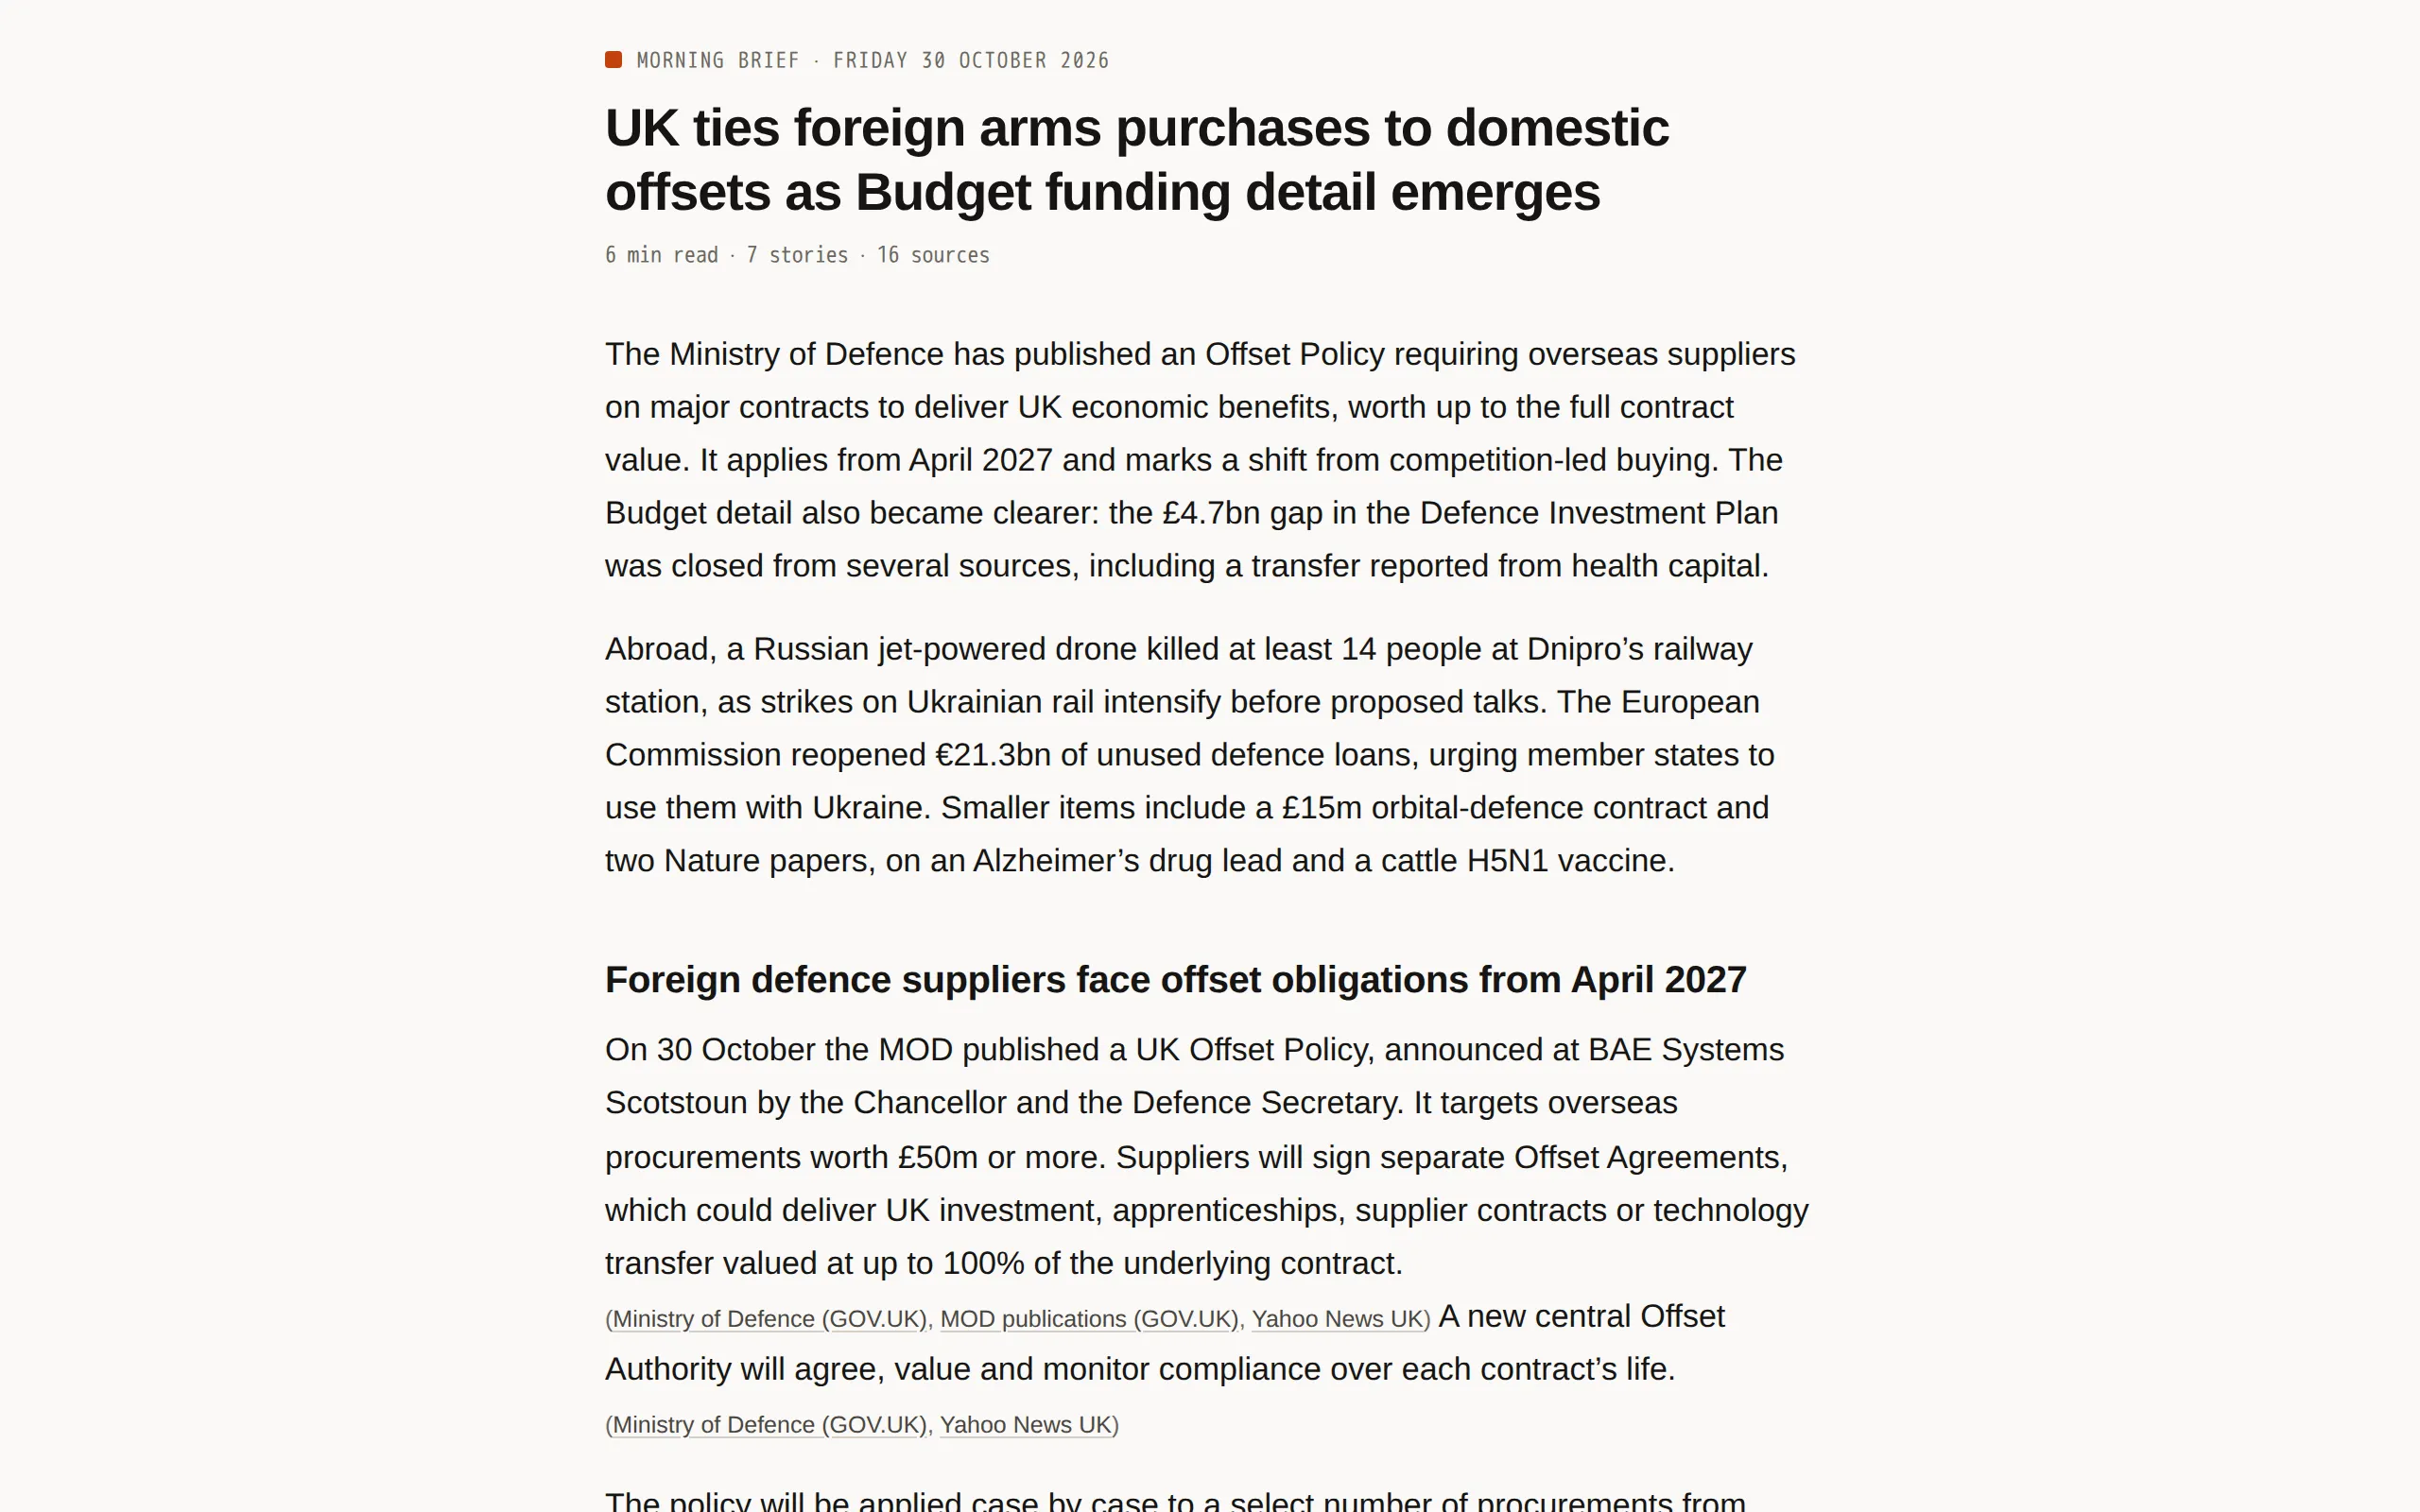
What it does
Every weekday morning I get one essay, usually a six- to ten-minute read, covering the news I care about: defence first, then AI, UK policy, geopolitics and science. Each story is summarised in plain prose, and every factual claim links to the reporting it came from. The same edition is published here, under Writing, a few minutes later.
It is written for any well-informed reader, not just me. My interests decide what gets selected and how much space it gets; they never appear in the text, so I can forward an edition without explaining it.
How it works
The pipeline runs in stages, each with the cheapest model that does the job well enough:
- Collect: every two hours, around 80 RSS feeds and Google News searches are fetched and the article text extracted.
- Triage: a cheap model scores each new article against a set of “desks” (defence, AI, UK policy and so on), each with its own weight and slot cap.
- Cluster: articles about the same event are grouped into one story.
- Brief: a mid-priced model writes a factual brief for each selected story, from the source text only.
- Write: Claude writes the edition from the briefs.
- Check: code checks every citation marker against the sources it was given, and a failed check gets one repair attempt before I’m alerted.
A small web editor on my tailnet lets me change the desks, sources and weights without touching YAML, and shows which desks and sources actually make it into editions.
The interesting problem
Cost. My first estimate was about $53 a month, which is a lot for a newsletter with one subscriber. Most of that was the writer model reading everything. The fix was structural rather than a cheaper writer: the expensive model only ever sees a handful of short briefs, and everything upstream (the thousands of triage calls) runs on models that cost a fraction of a cent. A cost ledger records every call by stage, and hard caps per run and per month stop a bug from becoming a bill. A typical edition now costs around 20 cents.
Choosing the writer was the other judgement call. I ran a blind comparison of Claude Opus against Sonnet for a week and preferred Sonnet three times out of five, at roughly half the cost. The test wasn’t perfectly blind (Opus’s version always arrived first, and Sonnet’s was consistently shorter), so I’d call that a reasonable decision rather than a proven one.
Stack and why
Python, because the hard parts (feed parsing and article extraction) have mature Python libraries. SQLite and a single container, because one reader does not need a database server. OpenRouter puts every model behind one API, so moving a stage to a different model is a config change. Resend handles delivery, and Uptime Kuma expects a heartbeat from every run, so a silent failure still gets noticed.
What I would do differently
I would design the model comparison before running it. Randomising the order and matching the length targets would have made the writer decision a proper test rather than an informed preference.
Stack
- Python 3.13 / uv
- Pipeline, CLI and config editor
- SQLite
- Articles, editions and the cost ledger
- OpenRouter
- One API for every model: GPT-6 Luna (triage, clustering), Gemini Flash (story briefs), Claude Sonnet 5.5 (writing)
- trafilatura + feedparser
- Feed collection and article text extraction
- Resend
- Email delivery
- supercronic + Uptime Kuma
- Schedule, and an alert if an edition doesn't arrive
- Docker Compose + Tailscale
- Deployment on my home server; the config editor is tailnet-only
~80
Feeds and searches
$0.20
Typical cost per edition
06:15
Delivered, Monday to Friday
- Editions
- Repository—private repository